sims-as-agent-benchmarks opportunity asserted
Simulation games as agent benchmarks
Use factory, colony, and economy sims as long-horizon evaluation and training environments for AI agents, with game studios as environment providers.
watch
2 shorts with this record on screen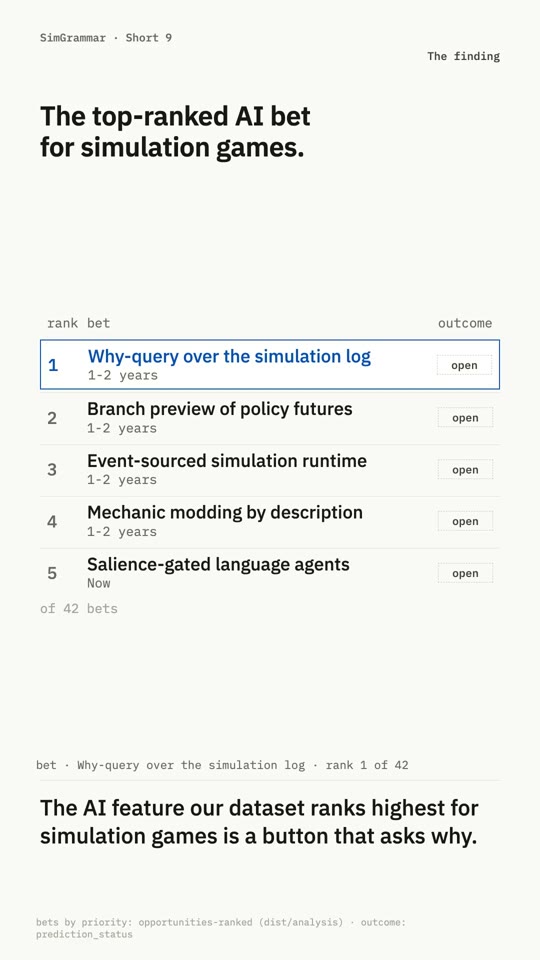 play · 0:39
short 9 0:39
The why button
transcript
The AI feature our dataset ranks highest for simulation games is a button that asks why.
We scored 42 bets on impact, feasibility, and novelty, and this one came first. Right-click the hospital that closed three months ago, ask why, and get a few sentences, each linked to an event in the game's own log. The model can only say what it can point to. If it can't ground an answer, it says so.
The bet has a deadline. If no game with at least ten thousand Steam reviews ships it by December 31, 2027, answering free-text questions from the player's own save, it loses.
also on the pages for
 play · 0:35
short 11 0:35
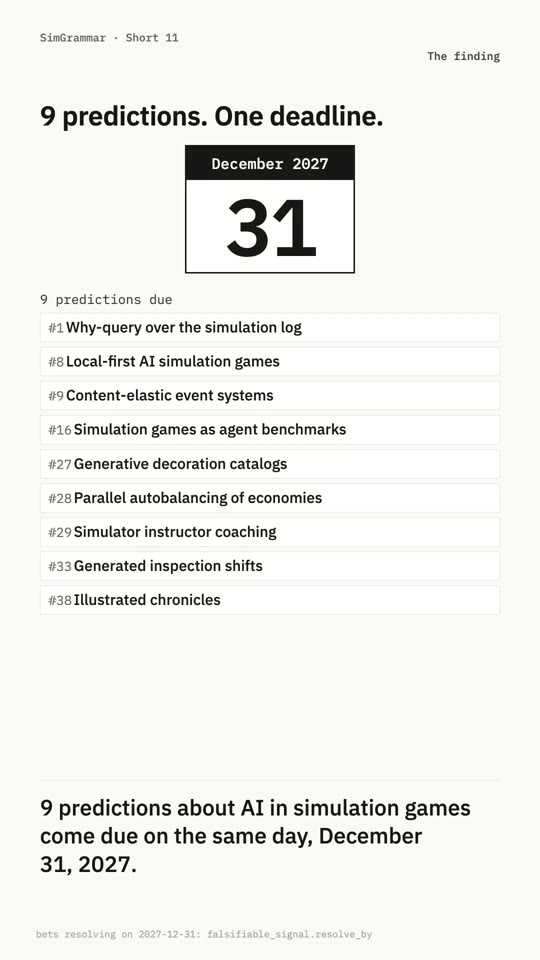
Due on the same day
transcript
9 predictions about AI in simulation games come due on the same day, December 31, 2027.
Every bet in our dataset carries one, written so a stranger could check it. Take the first: a widely played game lets you ask why something happened in your own save. It only counts if it shipped after October 24, 2026, in a game with ten thousand Steam reviews, answering from your save and not from a manual.
And the person who checks can't be the one who made the bet, or the same AI model that wrote it.
also on the pages for
thesis
AI agents now need environments that test planning over thousands of steps, resource management, and recovery from compounding errors. Simulation games are exactly that, with measurable outcomes (throughput, survival, profit). Minecraft became a research environment through MineDojo and Voyager, and factory games have been proposed as agent benchmarks. Games with headless modes and clean observation APIs can become a licensed research category.
design sketch
A studio ships a headless build with a typed observation and action API, standard scenarios, and leaderboards for agents. Researchers measure long-horizon performance; players watch agent runs as content.
validation experiment
Wrap an open-source colony or factory sim with a typed API, define five scenarios with throughput and survival metrics, and evaluate three frontier agents. Success: scores that separate agents and do not saturate within one model generation.
key risks
- Benchmarks saturate quickly.
- Studios may not want agent play to define their game publicly.
- Engine licensing for research use.
falsifiable prediction
A simulation game developer or publisher will officially release a headless research API or benchmark for AI agents.
Released after 2026-10-24 by the developer or publisher of a title with at least 1,000 Steam user reviews, as an official announcement or repository; community wrappers and academic forks do not count.